We ran into this the hard way. A product launch with generous defaults, a couple of power users, and a few gnarly retries from a flaky client added up to a five figure surprise. We needed per user and per model caps that held up under concurrency and failures.
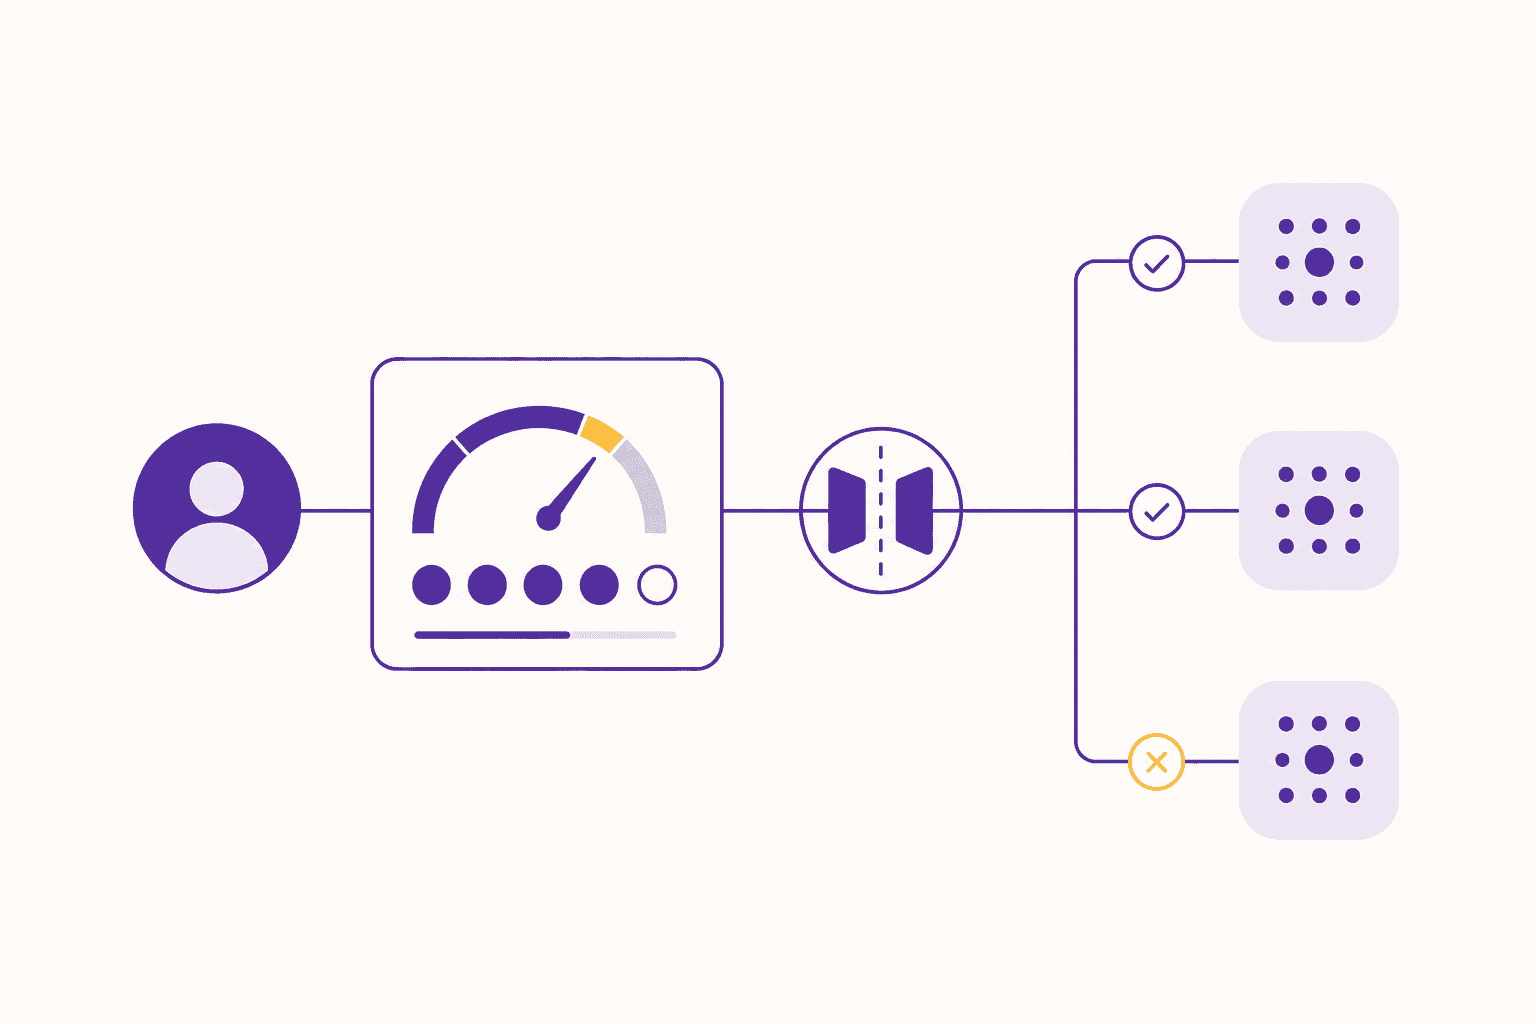
This is the pattern that worked. Meter precisely using provider usage, preflight with a conservative max cost, reserve budget atomically, then settle with actuals. If there is no budget, throttle or degrade gracefully. None of this is novel on its own. The trick is putting it together so engineers do not fight it during feature work.
If you are in the middle of shipping, you probably also care about the surrounding product plumbing. We cover that elsewhere in our work on AI features under our own AI product engineering approach.
What we actually need to constrain
The question everyone searches is how to cap LLM costs per user. What you really need is a budget keyed by tenant or user, by model, by time period. You need both a hard cap and a softer throttle to avoid spiky spend. You also need guardrails for retries and idempotency.
Constraints we found useful:
- Dimensions: user_id, model, period_start. Optional environment for test vs prod.
- Two periods: monthly cap for finance, daily soft cap for abuse control.
- Two phases: preflight reserve based on max cost, then settle with actual usage from the provider.
- Degradation: fallback to a cheaper model or smaller max_output_tokens when near the cap.
- Atomicity: no double charge on retries. No race conditions across concurrent requests.
We use Postgres for source of truth and Redis for fast atomic budget checks. We run this in Kubernetes with standard observability, which made it easy to roll out. If you need help around the infra side, we have written about similar rollouts in our Cloud and DevOps work.
Data model and pricing annotations
Put pricing in code, versioned, and auditable. Provider pricing changes, so load it from config at startup and tag your events with the version you used to compute estimates.
Schema we shipped:
-- Budgets are configured per user and model, with monthly caps in cents
create table llm_budgets (
  id bigserial primary key,
  user_id uuid not null,
  model text not null,
  month date not null, -- first day of month
  monthly_cap_cents integer not null,
  daily_soft_cap_cents integer not null,
  created_at timestamptz not null default now(),
  unique (user_id, model, month)
);

-- Ledger of actual usage, for audit and reconciliation
create table llm_usage_ledger (
  id bigserial primary key,
  user_id uuid not null,
  model text not null,
  period date not null, -- day
  request_id text not null, -- idempotency key
  prompt_tokens integer not null,
  completion_tokens integer not null,
  estimated_cents integer not null,
  actual_cents integer not null,
  pricing_version text not null,
  created_at timestamptz not null default now(),
  unique (user_id, model, period, request_id)
);
Keep a pricing table in code. Cost is per 1k tokens. Numbers below are examples, do not copy paste without verifying the latest pricing.
// pricing.ts
export type Pricing = { inputPer1k: number; outputPer1k: number };
export const PRICING_VERSION = "2025-01-10";
export const MODEL_PRICES: Record<string, Pricing> = {
  "gpt-4o-mini": { inputPer1k: 0.000150, outputPer1k: 0.000600 },
  "gpt-4o": { inputPer1k: 0.005000, outputPer1k: 0.015000 },
  "claude-3-5-sonnet": { inputPer1k: 0.003000, outputPer1k: 0.015000 },
  "claude-3-haiku": { inputPer1k: 0.000250, outputPer1k: 0.001250 }
};

export function estimateMaxCostCents(model: string, promptTokens: number, maxOutputTokens: number, margin = 1.15): number {
  const p = MODEL_PRICES[model];
  if (!p) throw new Error(`unknown model ${model}`);
  const inputCost = (promptTokens / 1000) * p.inputPer1k;
  const outputCost = (maxOutputTokens / 1000) * p.outputPer1k;
  return Math.ceil((inputCost + outputCost) * margin * 100);
}
We also annotate every request with the request_id that we use for idempotency. The client must send it. We reject requests without it. This one rule erased most double charges from retries.
Metering, preflight, and idempotency
We preflight by estimating the max cost, reserve that much budget atomically, then call the provider. After the response we settle by replacing the reservation with the actual cost from usage. If the process crashes between provider call and settlement, the reservation has a TTL and will expire, but we still have the provider response id to reconcile later.
The Redis keys we use:
- spend:user:{user_id}:{model}:month:{yyyymm} -> integer cents spent this month
- spend:user:{user_id}:{model}:day:{yyyymmdd} -> integer cents spent today
- resv:{request_id} -> integer cents reserved, with TTL 2 hours
Atomic check and reserve with a Lua script. The script enforces monthly and daily caps, applies idempotency, and increments counters only if within caps.
-- redis-reserve.lua
-- KEYS[1] = monthlySpendKey
-- KEYS[2] = dailySpendKey
-- KEYS[3] = reservationKey
-- ARGV[1] = reserveCents
-- ARGV[2] = monthlyCapCents
-- ARGV[3] = dailySoftCapCents
-- ARGV[4] = ttlSeconds

local reserve = tonumber(ARGV[1])
local monthCap = tonumber(ARGV[2])
local dayCap = tonumber(ARGV[3])
local ttl = tonumber(ARGV[4])

-- idempotent: if reservation exists, return its amount
local existing = redis.call('GET', KEYS[3])
if existing then
  return {1, tonumber(existing)}
end

local monthSpent = tonumber(redis.call('GET', KEYS[1]) or '0')
local daySpent = tonumber(redis.call('GET', KEYS[2]) or '0')

if monthSpent + reserve > monthCap then
  return {0, monthCap - monthSpent}
end
if daySpent + reserve > dayCap then
  return {0, dayCap - daySpent}
end

redis.call('SET', KEYS[3], reserve, 'EX', ttl)
redis.call('INCRBY', KEYS[1], reserve)
redis.call('INCRBY', KEYS[2], reserve)
return {1, reserve}
Settlement script to replace the reservation with actuals. It adjusts the monthly and daily spend by the delta between actual and reserved. It is also idempotent.
-- redis-settle.lua
-- KEYS[1] = monthlySpendKey
-- KEYS[2] = dailySpendKey
-- KEYS[3] = reservationKey
-- ARGV[1] = actualCents

local actual = tonumber(ARGV[1])
local reserved = tonumber(redis.call('GET', KEYS[3]) or '0')
if reserved == 0 then
  -- already settled or expired, nothing to do
  return {1, 0}
end
local delta = actual - reserved
if delta ~= 0 then
  redis.call('INCRBY', KEYS[1], delta)
  redis.call('INCRBY', KEYS[2], delta)
end
redis.call('DEL', KEYS[3])
return {1, delta}
Node middleware for preflight and settlement with OpenAI style usage, but the pattern is the same for Anthropic. Swap the client as needed. If you prefer to push this into a gateway instead, that is a reasonable trade off we discuss in our architecture review guidance.
// cost-guard.ts
import Redis from 'ioredis';
import { PRICING_VERSION, estimateMaxCostCents } from './pricing';
import OpenAI from 'openai';

const redis = new Redis(process.env.REDIS_URL!);
const openai = new OpenAI({ apiKey: process.env.OPENAI_API_KEY! });

function keys(userId: string, model: string, now: Date, requestId: string) {
  const yyyymm = now.toISOString().slice(0, 7).replace('-', '');
  const yyyymmdd = now.toISOString().slice(0, 10).replace(/-/g, '');
  return {
    month: `spend:user:${userId}:${model}:month:${yyyymm}`,
    day: `spend:user:${userId}:${model}:day:${yyyymmdd}`,
    resv: `resv:${requestId}`,
  };
}

type Caps = { monthlyCapCents: number; dailySoftCapCents: number };
async function loadCaps(userId: string, model: string, now: Date): Promise<Caps> {
  // Load from Postgres or config cache
  // Example static caps, replace with DB fetch
  return { monthlyCapCents: 5000, dailySoftCapCents: 500 }; // 50.00 monthly, 5.00 daily
}

export async function callWithCap(opts: {
  userId: string;
  model: string;
  requestId: string;
  system: string;
  messages: Array<{ role: 'user' | 'system' | 'assistant'; content: string }>;
  maxOutputTokens: number;
}) {
  const now = new Date();
  const { userId, model, requestId, system, messages, maxOutputTokens } = opts;
  if (!requestId) throw new Error('missing request_id');

  const promptTokens = await roughTokenCount(model, system, messages); // fast estimator, see note below
  const tentativeCents = estimateMaxCostCents(model, promptTokens, maxOutputTokens);
  const { monthlyCapCents, dailySoftCapCents } = await loadCaps(userId, model, now);
  const { month, day, resv } = keys(userId, model, now, requestId);

  const reserveResult = await redis.evalsha(
    await loadScript(redis, 'reserve'),
    3,
    month,
    day,
    resv,
    tentativeCents,
    monthlyCapCents,
    dailySoftCapCents,
    7200 // 2 hours
  );
  const [ok, reserved] = reserveResult as [number, number];
  if (!ok) {
    const remaining = reserved; // negative or zero means no room left
    const err = new Error(`budget_exceeded remaining=${remaining}`);
    (err as any).code = 'BUDGET_EXCEEDED';
    throw err;
  }

  // Call provider with conservative max output tokens
  const resp = await openai.chat.completions.create({
    model,
    messages: [{ role: 'system', content: system }, ...messages],
    max_tokens: maxOutputTokens,
    temperature: 0.2,
  });

  const usage = resp.usage || { prompt_tokens: promptTokens, completion_tokens: maxOutputTokens };
  const actualCents = estimateActualCents(model, usage.prompt_tokens, usage.completion_tokens);

  // Settle
  const settleResult = await redis.evalsha(
    await loadScript(redis, 'settle'),
    3,
    month,
    day,
    resv,
    actualCents
  );

  // Persist to ledger asynchronously
  void persistLedger({
    userId,
    model,
    requestId,
    promptTokens: usage.prompt_tokens,
    completionTokens: usage.completion_tokens,
    estimatedCents: tentativeCents,
    actualCents,
    pricingVersion: PRICING_VERSION,
  });

  return resp;
}

function estimateActualCents(model: string, prompt: number, completion: number): number {
  const p = MODEL_PRICES[model as keyof typeof MODEL_PRICES];
  const inputCost = (prompt / 1000) * p.inputPer1k;
  const outputCost = (completion / 1000) * p.outputPer1k;
  return Math.round((inputCost + outputCost) * 100);
}

async function roughTokenCount(model: string, system: string, messages: any[]): Promise<number> {
  // Use a fast BPE approximator or cached tokenizer per model
  // Fallback to a heuristic of 4 chars per token
  const text = [system, ...messages.map(m => m.content)].join('\n');
  return Math.ceil(text.length / 4);
}

const SCRIPTS: Record<string, { sha?: string; src: string }> = {
  reserve: { src: require('fs').readFileSync('./redis-reserve.lua', 'utf8') },
  settle: { src: require('fs').readFileSync('./redis-settle.lua', 'utf8') },
};
async function loadScript(r: Redis, name: 'reserve' | 'settle') {
  if (SCRIPTS[name].sha) return SCRIPTS[name].sha;
  const sha = await r.script('load', SCRIPTS[name].src);
  SCRIPTS[name].sha = sha;
  return sha;
}

async function persistLedger(row: any) {
  // insert into Postgres, omit here
}
A few practical notes:
- Always set max_output_tokens. Unlimited completions make preflight meaningless.
- Use a margin above the estimated max cost. We use 15 percent. Tweak based on your model mix and retry behavior.
- Do not block the response on ledger persistence. Buffer and retry on failure. We batch inserts per second.
- If you use multiple providers behind an abstraction, add provider_id to keys and ledger. For teams with heavy integrations, we keep these glue layers simple and modular. Our experience on large API programs shows the benefit, which we cover under API system integrations.
Throttling by cost, not just requests
Hard caps prevent overruns but do not smooth bursty spend. We add a cost based token bucket. Instead of tokens as requests, tokens are cents. Buckets refill over time up to a ceiling, which encodes your desired burn rate.
We keep a cost bucket per user and model. Refill rate is daily_soft_cap_cents divided by 86,400 seconds. Ceiling is daily_soft_cap_cents. Before each call we try to consume tentativeCents. If it fails, we either delay, degrade, or reject.
-- redis-cost-bucket.lua
-- KEYS[1] = bucketKey
-- ARGV[1] = nowMs
-- ARGV[2] = refillRateCentsPerSec (float)
-- ARGV[3] = bucketMaxCents
-- ARGV[4] = chargeCents
-- State: value= currentCents, lastTsMs
local now = tonumber(ARGV[1])
local rate = tonumber(ARGV[2])
local maxv = tonumber(ARGV[3])
local charge = tonumber(ARGV[4])

local data = redis.call('HMGET', KEYS[1], 'v', 'ts')
local v = tonumber(data[1]) or maxv
local ts = tonumber(data[2]) or now

local elapsed = math.max(0, now - ts) / 1000.0
v = math.min(maxv, v + elapsed * rate)
if v < charge then
  redis.call('HMSET', KEYS[1], 'v', v, 'ts', now)
  redis.call('PEXPIRE', KEYS[1], 86400000)
  return {0, math.ceil((charge - v) / rate)} -- not enough, seconds until available
end
v = v - charge
redis.call('HMSET', KEYS[1], 'v', v, 'ts', now)
redis.call('PEXPIRE', KEYS[1], 86400000)
return {1, v}
In the request flow, run the bucket check before the reservation. If the bucket says wait 12 seconds, you can either sleep on the server side, respond with 429 and a Retry-After header, or switch to a cheaper model with a smaller tentativeCents.
Degradation we shipped:
- If cost bucket blocks, cut max_output_tokens by 50 percent and retry bucket.
- If still blocked, switch to a cheaper model for this tier. Example sonnet to haiku.
- If still blocked, reject with 429 Too Many Requests and include a diagnostic on expected wait.
Avoid silent degradation for paid tiers unless your product specifically allows it. Tie this into feature flags so product can tune the policy without redeploy.
Failure modes and how we hardened it
We broke this a few times in staging. The issues and what fixed them:
- Double charging on client retries. Fix: require request_id from the client, use it as the reservation key, and make all writes idempotent. If you do not control the client, generate a surrogate id from a hash of normalized input.
- Capacity jitter across pods. Fix: no in memory counters. Only Redis with Lua is allowed to move balances. Everything else is read only.
- Month rollover bugs. Fix: keys include the period. We update the month key on the first write of the month and set TTL to slightly longer than a month to avoid accidental expiration. We also create the new month ledger rows on the first day.
- Provider timeouts during settlement. Fix: settlement uses actual usage from the response if present, not a second API call. If the provider never returned usage, we settle to the reserved amount and mark a flag for reconciliation.
- Price changes mid month. Fix: pricing_version is part of every ledger row. Reconciliation uses the version that was applied at the time.
If your environment has stronger compliance constraints, you will also want a periodic reconciliation job that totals Redis and Postgres and raises an alert on drift. We run that every 10 minutes and page at 50 cents drift. If you are in a regulated space like healthtech, keep your threat model tight. We covered operational controls for sensitive stacks in our piece on security aware engineering practices.
Observability and testing in anger
You need to see spend and headroom at a glance. We log a compact event on reserve and settle with these fields: user_id, model, request_id, tentative_cents, actual_cents, caps, remaining_month, remaining_day, bucket_remaining, decision. That feeds metrics:
- llm_spend_cents_total{user,model}
- llm_reservations_inflight{user}
- llm_budget_denials_total{user,reason}
- llm_bucket_wait_seconds{user}
- llm_degradation_events_total{user,type}
We wrote runnable tests that fork 50 workers firing at the same budget and verified no negative balances and no over caps. For a first pass, you can script this locally against a dev Redis, then move it under your CI. If you want a second set of eyes on the whole release pipeline, we have a straightforward engineering process setup checklist that maps how we gate changes like this.
What we would do differently next time
- Move pricing and caps to a control plane service backed by Postgres that pushes config to a Redis cache. The code above calls straight into Redis which is fine for one service, but a control plane makes it easier to change policy without deploys.
- Add product tier limits alongside per model caps so we can default smarter. Today, a user on Standard might have 5 dollars on gpt-4o and 2 dollars on claude-haiku. It would be better to declare 7 dollars total across models and a priority order for consumption.
- Push the cost bucket to the edge. If you run a global CDN or gateway, evaluating the bucket early would shave p99s for blocked calls.
- Share headroom with the client. If the client knew it had 0.23 left today, it could choose a smaller prompt or a faster cheaper model. That also reduces frustration when a call is blocked.
If you are wrestling with this while a feature is hot, your priority is shipping without exploding the budget. The pattern above is the smallest set of moving parts that held up under production load for us. If you need to map it cleanly into your stack and environment, especially when you already have a busy service mesh and event bus, our team handles this kind of plumbing in parallel with delivery as part of our AI product engineering work. For broader systems concerns like limits across many services and providers, we usually start with a fast architecture review and pull in our Cloud and DevOps practice where rate limiters and Redis ops matter.
Appendix: rough tokenization
Preflight needs a quick token estimate. We use tiktoken or Claude tokenizers where available, behind an interface that falls back to a heuristic. Cache by model and message hash for repeat prompts. That takes the estimator from 2 ms to sub 200 microseconds in our traces.
Finally, if you are integrating this across a legacy estate and multiple microservices, resist the urge to build a massive shared library. Keep the budget policy in a small service with HTTP endpoints that others can call. That architecture keeps coupling under control. We have taken similar approaches in large fleets, as documented in our notes on API system integrations.